Planning Your Configuration
Last updated: October 21, 2026
| Tier | Deployment |
|
|
Tip: Already have a Kubernetes cluster? You can install Sisense with Helm directly, without sisense.sh, a Linux install host, an SSH key, or sudo. See Installing Sisense with Helm on an Existing Cluster (Multinode/Cloud) and Choosing an Installation Method.
Sisense supports two deployment topologies on Linux: a single-node deployment, and a multi-node deployment. This page describes the two supported deployments and the differences between them.
Before you plan the topology, choose how you will install Sisense: with the sisense.sh installer, with the Provisioner, or with Helm directly. The method determines where you need a Linux user, SSH access, and sudo, and which Kubernetes permissions you need. See Choosing an Installation Method and Privileges and Permissions for Self-Deployment.
In both deployments, the Sisense application is provided as Docker containers. The orchestration between these
containers is managed through Kubernetes as displayed in the diagram below.
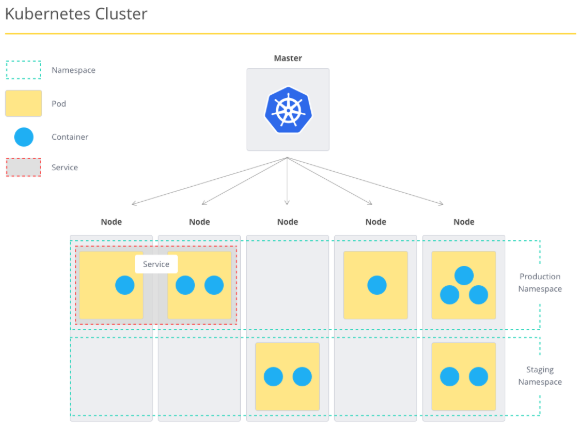
This diagram illustrates how Sisense utilizes Kubernetes for redundancy and load balancing regardless of the number of machines. When you initialize Sisense, it is installed as a Kubernetes namespace. The services and ElastiCubes that make up the Sisense application are pods spread across the node or nodes in your deployment.
Single-Node
In its most basic configuration, Sisense can run on a single Linux machine. The deployment scenario is straightforward to set up, maintain, and upgrade.
The single server deployment will deploy all Sisense nodes on a single server using Kubernetes orchestration. It can support a sandbox environment for development and testing, but it is also a valid configuration for some production environments.
The deployment will utilize the storage available locally on the host server.
Important:
In a Single-Node deployment, Sisense supports up to 135 simultaneously running data models (ElastiCubes and Live models combined). Exceeding this limit exhausts the node's available ephemeral storage, causing model pods to remain in a Pending state and fail to schedule.
Multi-Node
Sisense supports the configuration of multiple machines, or nodes. In a multiple node deployment, you have one build-node, two application/query nodes. You can add additional build and query nodes as needed. In addition, Sisense supports shared storage.
As with a single-node deployment, Kubernetes is used to manage the orchestration of Docker containers across a namespace. Kubernetes is also used for load balancing within the Sisense deployment.
The minimum deployment size for a Sisense multi-server deployment is three servers. In three server deployments, two servers will each run as an application and query node. The third server will run as the build node.
In a basic three server deployment, one of the servers is a dedicated build node. The other two servers both provide the functionality of an application and a query node. The infrastructure services must be deployed on each of the three servers, to adequately provide high-availability and redundancy of the infrastructure modules. Additional query and build nodes can be added to the deployment, to support additional load.
Sisense uses Helm to deploy the Sisense application. Kubernetes loads the Sisense pods on the correct nodes based on node labels:
-
When you install with sisense.sh, the installer labels each node according to the roles that you assign to it in
k8s_nodes:node-<namespace>-Application=true,node-<namespace>-Query=true, andnode-<namespace>-Build=true. The installer does not label nodes on OpenShift, whencluster_visibility: false, or whenskip_labeling: true. -
The Sisense Helm chart does not add these labels. It only selects nodes by label: in a multi-node deployment, Sisense pods run only on nodes labeled
node-<namespace>-Application=true(case-sensitive). If you install with Helm, or the installer does not label your nodes, label them yourself. On a managed Kubernetes service, set the label on the node pool, so that nodes that the autoscaler adds or replaces also get it.
Kubernetes also places ElastiCubes on each node according to dynamic labels given in the data group.
See About Multi-Node Deployments.